Blog

Latest news and updates from LLM Gateway

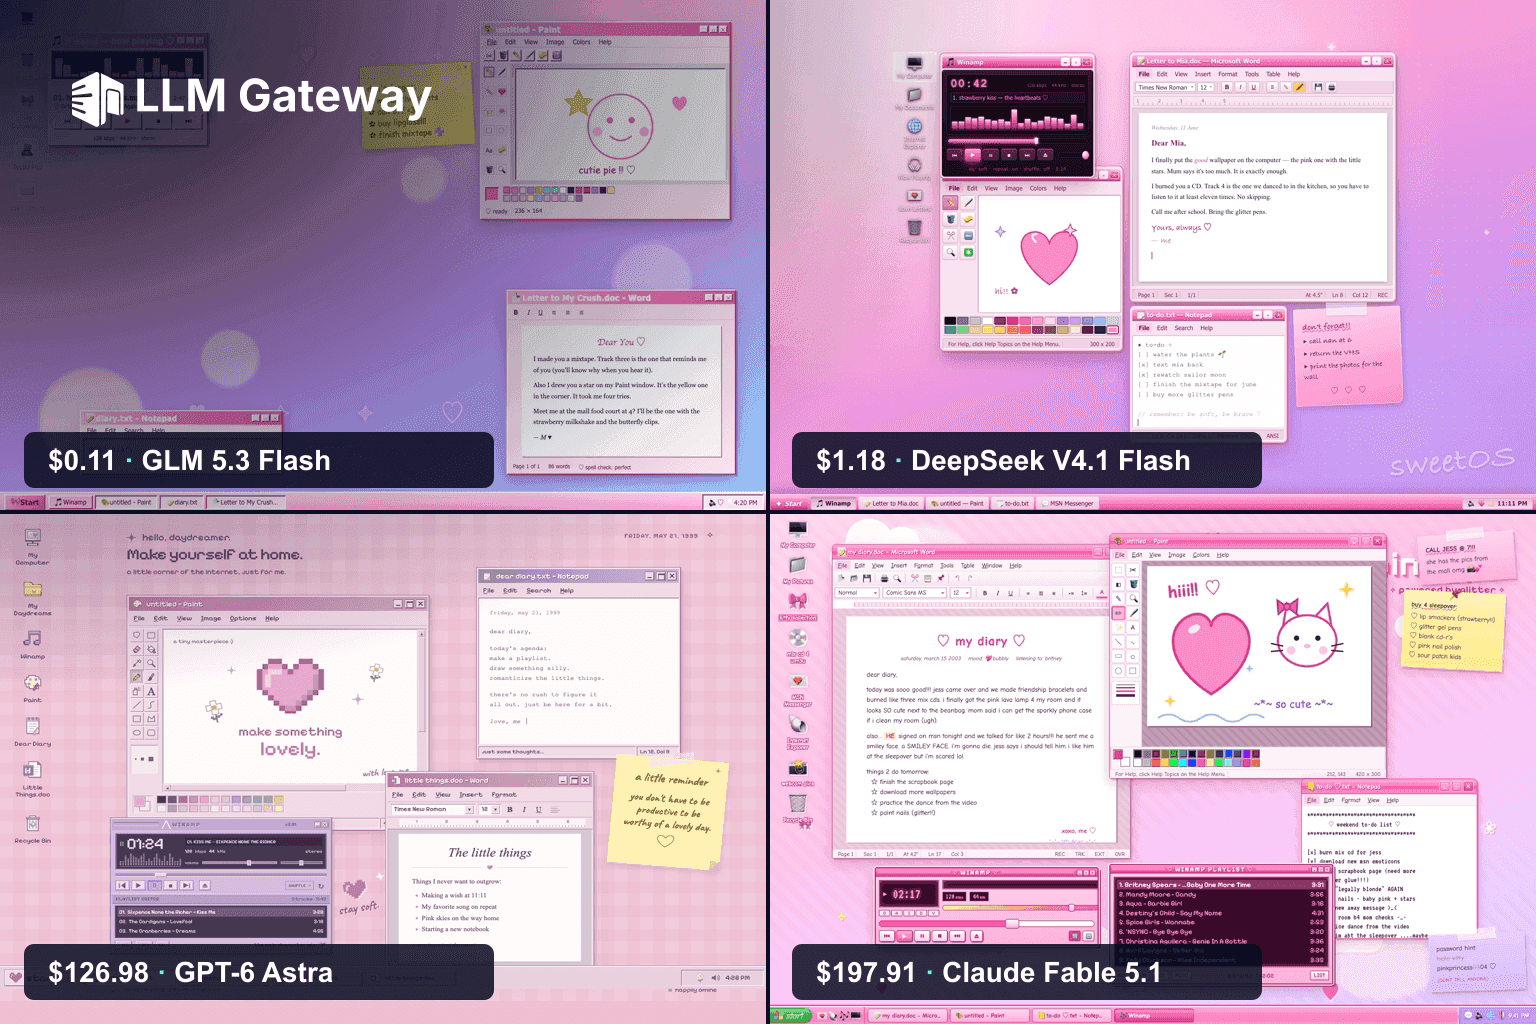
Four pink retro Windows desktops built by different AI models, in a 2x2 grid labelled with what each run cost: $0.11, $1.18, $126.98 and $197.91

Cheap vs Flagship AI Models: $0.10 vs $198

We gave six models the same coding task and measured what each one actually cost. The cheapest produced a working result for 10 cents. The most expensive spent $198 on a single index.html. This AI coding model benchmark shows where the money goes and where it stops buying quality.

September 14, 2026
A glowing boarding-gate arch on a central chip with a lit checklist beside it and light traces leading in from the edge of a circuit board, surrounded by a key, a plug, and a document icon

How to Get Your LLM API Listed on an AI Gateway

A checklist for inference providers who want their LLM API listed on an AI gateway: domain ownership, an OpenAI-compatible endpoint the gateway can actually call, honest capability flags, streaming that reports usage, flat per-million pricing, and rate limits you can sustain. Written against LLM Gateway's Airside listing process.

September 13, 2026
A glowing dispatch radar on a central chip with light traces splitting toward three provider gates on a circuit board, surrounded by a stopwatch, a price tag, and an uptime gauge

How LLM Routing Picks a Provider: A Carrier's Guide

LLM routing on LLM Gateway is an election: every provider listing a model is scored on effective price, uptime, throughput, and latency, and the lowest score wins. This guide explains the scoring from the provider's side, with the fare formula, the uptime penalty, cache-aware pricing, and the levers a carrier controls from Airside.

September 13, 2026
A glowing balance scale weighing coins against a memory-cache module on a circuit board, with light traces routing toward two provider chips

Cache-Aware LLM Routing Learns Your Workload

Cache-aware LLM routing learns cache-hit rates and token proportions from your project's recent model usage, so provider selection reflects the workload you actually run. Available automatically across plans, with explicit per-project overrides on Enterprise.

September 5, 2026
A circuit board with a glowing doorway on the central chip, representing a drop-in Vercel AI Gateway alternative for the AI SDK

A Vercel AI Gateway Alternative Without the Rewrite

Switching off the Vercel AI Gateway used to mean rewriting how your AI SDK app resolves models — and losing provider-native web search on the way out. LLM Gateway now implements the AI SDK's own gateway protocol, so the migration is one line and your bare model strings keep working.

August 12, 2026
A circuit board with a glowing stopwatch on the central chip surrounded by a podium and rising bar chart, representing AI gateway latency benchmarks

Ranked #1 on an Independent AI Gateway Benchmark

In the August 7 run of computesdk's independent AI gateway benchmark, LLM Gateway ranked first of six gateways with a composite score of 90.8 — driven by the tightest tail latency in the field, not the fastest median. Here's what the benchmark measures, what our numbers actually show, and how to run it yourself.

August 8, 2026
Glossy circuit board with a glowing stopwatch on the central chip and light traces racing toward it, representing an AI gateway latency benchmark

OpenRouter vs Vercel vs LLMGateway Performance

We measured AI gateway performance with an open-source TTFT benchmark: 75 cold + 75 warm interleaved runs of claude-haiku-4.5 against LLM Gateway and OpenRouter, with phase-by-phase timings and raw data published. LLM Gateway reached first token ~35% faster cold and ~34% faster warm, and here is exactly how to reproduce the numbers.

July 22, 2026